Skip to content
iLab: From Brain to Machine and Back

iLab: From Brain to Machine and Back

iossifidis Lab

  • Home
  • Research Projects
  • Publications
  • Software
  • Press and Media
  • Student’s Zone — Teaching
    • Thesis topics
    • Student Projects
    • Journal Club & Progress Club
    • Lab Course
    • Lectures – Vorlesungen
  • About us
    • The Team
    • Contact
    • Impressum
  • Home
  • Publications

Publications

Anthropomorphic Robot arm movement model attractor dynamics approach attractor dynamics approach BCI behavior generation collision avoidance direct physical interaction dynamic neural field dynamical systems EEG haptic interface human robot collaboration image processing Inverse kinematics Machine Learning man machine interaction Man-machine-interaction manipulator dynamics movement model recurrent neural network redundant robot arm Reinforcement learning Robot manipulator control Robotics Robotics scene representation simulated reality Simulation speech recognition

Show all

2026

3.
Invariance to~Quantile Selection in~Distributional Continuous Control

Felix Grün; Muhammad Saif-ur-Rehman; Tobias Glasmachers; Ioannis Iossifidis

Invariance to~Quantile Selection in~Distributional Continuous Control Inproceedings

In: Nicosia, Giuseppe; Ojha, Varun; Giesselbach, Sven; Pardalos, M. Panos; Umeton, Renato; Emanuele, La Malfa; Gabriele, La Malfa (Ed.): Machine Learning, Optimization, and Data Science, pp. 175–190, Springer Nature Switzerland, Cham, 2026, ISBN: 978-3-032-21477-5.

Abstract | Links | BibTeX | Tags: Actor-critic, BCI, Continuous control, Distributional reinforcement learning, Machine Learning, Quantile regression, reinforcement learning (RL)

@inproceedings{grunInvarianceQuantileSelection2026,
title = {Invariance to~Quantile Selection in~Distributional Continuous Control},
author = {Felix Grün and Muhammad Saif-ur-Rehman and Tobias Glasmachers and Ioannis Iossifidis},
editor = {Giuseppe Nicosia and Varun Ojha and Sven Giesselbach and M. Panos Pardalos and Renato Umeton and La Malfa Emanuele and La Malfa Gabriele},
doi = {10.1007/978-3-032-21477-5_12},
isbn = {978-3-032-21477-5},
year = {2026},
date = {2026-06-01},
urldate = {2026-06-01},
booktitle = {Machine Learning, Optimization, and Data Science},
pages = {175–190},
publisher = {Springer Nature Switzerland},
address = {Cham},
abstract = {In recent years, distributional reinforcement learning has produced many state-of-the-art results in typical reinforcement learning benchmarks, such as the suite of Atari games. Increasingly sample-efficient distributional algorithms for the discrete action domain have been developed over time, which vary primarily in the way they parameterize their approximations of value distributions, and how they quantify the differences between those distributions. In this work, we transfer three of those algorithms - Quantile Regression Deep Q-Network (QR-DQN), Implicit Quantile Networks (IQN) and Fully Parameterized Quantile Function (FQF) - to the continuous action domain by extending two powerful actor-critic algorithms - Twin Delayed Deep Deterministic policy gradient (TD3) and Soft Actor-Critic (SAC) - with distributional critics. We investigate whether the relative performance of the methods for the discrete action space translates to the continuous case. To that end, we compare them empirically on a set of continuous control tasks (Ant, HalfCheetah, Hopper, Humanoid and Walker2D). Our results indicate qualitative invariance regarding the number and placement of distributional atoms in the deterministic, continuous action setting.},
keywords = {Actor-critic, BCI, Continuous control, Distributional reinforcement learning, Machine Learning, Quantile regression, reinforcement learning (RL)},
pubstate = {published},
tppubtype = {inproceedings}
}
Close

In recent years, distributional reinforcement learning has produced many state-of-the-art results in typical reinforcement learning benchmarks, such as the suite of Atari games. Increasingly sample-efficient distributional algorithms for the discrete action domain have been developed over time, which vary primarily in the way they parameterize their approximations of value distributions, and how they quantify the differences between those distributions. In this work, we transfer three of those algorithms - Quantile Regression Deep Q-Network (QR-DQN), Implicit Quantile Networks (IQN) and Fully Parameterized Quantile Function (FQF) - to the continuous action domain by extending two powerful actor-critic algorithms - Twin Delayed Deep Deterministic policy gradient (TD3) and Soft Actor-Critic (SAC) - with distributional critics. We investigate whether the relative performance of the methods for the discrete action space translates to the continuous case. To that end, we compare them empirically on a set of continuous control tasks (Ant, HalfCheetah, Hopper, Humanoid and Walker2D). Our results indicate qualitative invariance regarding the number and placement of distributional atoms in the deterministic, continuous action setting.

Close

  • doi:10.1007/978-3-032-21477-5_12

Close

2.
Performance Boundaries for~Brain-Computer Interfaces Using Error-Related Potentials and~Reinforcement Learning

Aline Xavier Fidêncio; Felix Grün; Christian Klaes; Ioannis Iossifidis

Performance Boundaries for~Brain-Computer Interfaces Using Error-Related Potentials and~Reinforcement Learning Inproceedings

In: Nicosia, Giuseppe; Ojha, Varun; Giesselbach, Sven; Pardalos, M. Panos; Umeton, Renato; Emanuele, La Malfa; Gabriele, La Malfa (Ed.): Machine Learning, Optimization, and Data Science, pp. 335–349, Springer Nature Switzerland, Cham, 2026, ISBN: 978-3-032-21480-5.

Abstract | Links | BibTeX | Tags: adaptive brain-computer interface, BCI, electroencephalography (EEG), error-related potentials (ErrPs), Machine Learning, motor imagery (MI), reinforcement learning (RL)

@inproceedings{xavierfidencioPerformanceBoundariesBrainComputer2026,
title = {Performance Boundaries for~Brain-Computer Interfaces Using Error-Related Potentials and~Reinforcement Learning},
author = {Aline Xavier Fidêncio and Felix Grün and Christian Klaes and Ioannis Iossifidis},
editor = {Giuseppe Nicosia and Varun Ojha and Sven Giesselbach and M. Panos Pardalos and Renato Umeton and La Malfa Emanuele and La Malfa Gabriele},
doi = {10.1007/978-3-032-21480-5_23},
isbn = {978-3-032-21480-5},
year = {2026},
date = {2026-06-01},
urldate = {2026-06-01},
booktitle = {Machine Learning, Optimization, and Data Science},
pages = {335–349},
publisher = {Springer Nature Switzerland},
address = {Cham},
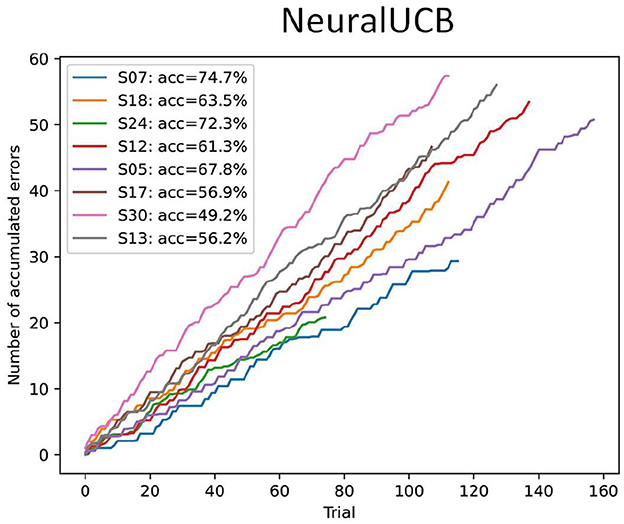
abstract = {Non-invasive brain-computer interfaces (BCIs) can improve quality of life for individuals with motor disabilities. However, input data non-stationarity often leads to performance degradation over time. Adaptive BCIs aim to address this challenge. Recent studies have proposed leveraging error-related potentials (ErrPs) - neural signals elicited during self-made or observed errors - as a natural feedback mechanism for closed-loop systems. While these approaches demonstrate potential performance gains, their effectiveness relies heavily on accurate ErrP detection, which remains challenging. In a previous study, we introduced a novel reinforcement learning-based BCI framework incorporating ErrPs as reward signals. We systematically examine how misclassification rates in ErrP detection in terms of false positives (FPs) and false negatives (FNs) influence closed-loop performance. We use both synthetic and real datasets to evaluate two contextual bandit algorithms (LinUCB and NeuralUCB), trained to map motor imagery-related time-frequency modulations to actions in a binary task. Firstly, our findings show that the sensitivity of agents to FPs and FNs depends on baseline accuracies. In some conditions, such as insufficient exploration, false negatives might be more detrimental than false positives, but this needs further investigation. Proper agent parametrization and enough data samples can compensate the negative effects to some extent.},
keywords = {adaptive brain-computer interface, BCI, electroencephalography (EEG), error-related potentials (ErrPs), Machine Learning, motor imagery (MI), reinforcement learning (RL)},
pubstate = {published},
tppubtype = {inproceedings}
}

Close

Non-invasive brain-computer interfaces (BCIs) can improve quality of life for individuals with motor disabilities. However, input data non-stationarity often leads to performance degradation over time. Adaptive BCIs aim to address this challenge. Recent studies have proposed leveraging error-related potentials (ErrPs) - neural signals elicited during self-made or observed errors - as a natural feedback mechanism for closed-loop systems. While these approaches demonstrate potential performance gains, their effectiveness relies heavily on accurate ErrP detection, which remains challenging. In a previous study, we introduced a novel reinforcement learning-based BCI framework incorporating ErrPs as reward signals. We systematically examine how misclassification rates in ErrP detection in terms of false positives (FPs) and false negatives (FNs) influence closed-loop performance. We use both synthetic and real datasets to evaluate two contextual bandit algorithms (LinUCB and NeuralUCB), trained to map motor imagery-related time-frequency modulations to actions in a binary task. Firstly, our findings show that the sensitivity of agents to FPs and FNs depends on baseline accuracies. In some conditions, such as insufficient exploration, false negatives might be more detrimental than false positives, but this needs further investigation. Proper agent parametrization and enough data samples can compensate the negative effects to some extent.

Close

  • doi:10.1007/978-3-032-21480-5_23

Close

2025

1.
Hybrid Brain-Computer Interface Using Error-Related Potential and Reinforcement Learning

Aline Xavier Fidêncio; Felix Grün; Christian Klaes; Ioannis Iossifidis

Hybrid Brain-Computer Interface Using Error-Related Potential and Reinforcement Learning Journal Article

In: Frontiers in Human Neuroscience, vol. 19, 2025, ISSN: 1662-5161.

Abstract | Links | BibTeX | Tags: adaptive brain-computer interface, BCI, EEG, error-related potentials (ErrPs), Machine Learning, motor imagery (MI), reinforcement learning (RL)

@article{xavierfidencioHybridBraincomputerInterface2025,
title = {Hybrid Brain-Computer Interface Using Error-Related Potential and Reinforcement Learning},
author = {Aline Xavier Fidêncio and Felix Grün and Christian Klaes and Ioannis Iossifidis},
editor = {Frontiers},
url = {https://www.frontiersin.org/journals/human-neuroscience/articles/10.3389/fnhum.2025.1569411/full},
doi = {10.3389/fnhum.2025.1569411},
issn = {1662-5161},
year = {2025},
date = {2025-06-04},
urldate = {2025-06-04},
journal = {Frontiers in Human Neuroscience},
volume = {19},
publisher = {Frontiers},
abstract = {Brain-computer interfaces (BCIs) offer alternative communication methods for individuals with motor disabilities, aiming to improve their quality of life through external device control. However, non-invasive BCIs using electroencephalography (EEG) often suffer from performance limitations due to non-stationarities arising from changes in mental state or device characteristics. Addressing these challenges motivates the development of adaptive systems capable of real-time adjustment. This study investigates a novel approach for creating an adaptive, error-related potential (ErrP)-based BCI using reinforcement learning (RL) to dynamically adapt to EEG signal variations. The framework was validated through experiments on a publicly available motor imagery dataset and a novel fast-paced protocol designed to enhance user engagement. Results showed that RL agents effectively learned control policies from user interactions, maintaining robust performance across datasets. However, findings from the game-based protocol revealed that fast-paced motor imagery tasks were ineffective for most participants, highlighting critical challenges in real-time BCI task design. Overall, the results demonstrate the potential of RL for enhancing BCI adaptability while identifying practical constraints in task complexity and user responsiveness.},
keywords = {adaptive brain-computer interface, BCI, EEG, error-related potentials (ErrPs), Machine Learning, motor imagery (MI), reinforcement learning (RL)},
pubstate = {published},
tppubtype = {article}
}

Close

Brain-computer interfaces (BCIs) offer alternative communication methods for individuals with motor disabilities, aiming to improve their quality of life through external device control. However, non-invasive BCIs using electroencephalography (EEG) often suffer from performance limitations due to non-stationarities arising from changes in mental state or device characteristics. Addressing these challenges motivates the development of adaptive systems capable of real-time adjustment. This study investigates a novel approach for creating an adaptive, error-related potential (ErrP)-based BCI using reinforcement learning (RL) to dynamically adapt to EEG signal variations. The framework was validated through experiments on a publicly available motor imagery dataset and a novel fast-paced protocol designed to enhance user engagement. Results showed that RL agents effectively learned control policies from user interactions, maintaining robust performance across datasets. However, findings from the game-based protocol revealed that fast-paced motor imagery tasks were ineffective for most participants, highlighting critical challenges in real-time BCI task design. Overall, the results demonstrate the potential of RL for enhancing BCI adaptability while identifying practical constraints in task complexity and user responsiveness.

Close

  • https://www.frontiersin.org/journals/human-neuroscience/articles/10.3389/fnhum.2[...]
  • doi:10.3389/fnhum.2025.1569411

Close

Leave a Reply Cancel reply

Your email address will not be published. Required fields are marked *

Copyright © Ioannis Iossifidis 2020 iLab: From Brain to Machine and Back.

Theme: Oceanly by ScriptsTown

We use cookies on our website to give you the most relevant experience by remembering your preferences and repeat visits. By clicking “Accept All”, you consent to the use of ALL the cookies. However, you may visit "Cookie Settings" to provide a controlled consent.
Cookie SettingsAccept All
Manage consent

Privacy Overview

This website uses cookies to improve your experience while you navigate through the website. Out of these, the cookies that are categorized as necessary are stored on your browser as they are essential for the working of basic functionalities of the website. We also use third-party cookies that help us analyze and understand how you use this website. These cookies will be stored in your browser only with your consent. You also have the option to opt-out of these cookies. But opting out of some of these cookies may affect your browsing experience.
Necessary
Always Enabled
Necessary cookies are absolutely essential for the website to function properly. These cookies ensure basic functionalities and security features of the website, anonymously.
CookieDurationDescription
cookielawinfo-checkbox-analytics11 monthsThis cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category "Analytics".
cookielawinfo-checkbox-functional11 monthsThe cookie is set by GDPR cookie consent to record the user consent for the cookies in the category "Functional".
cookielawinfo-checkbox-necessary11 monthsThis cookie is set by GDPR Cookie Consent plugin. The cookies is used to store the user consent for the cookies in the category "Necessary".
cookielawinfo-checkbox-others11 monthsThis cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category "Other.
cookielawinfo-checkbox-performance11 monthsThis cookie is set by GDPR Cookie Consent plugin. The cookie is used to store the user consent for the cookies in the category "Performance".
viewed_cookie_policy11 monthsThe cookie is set by the GDPR Cookie Consent plugin and is used to store whether or not user has consented to the use of cookies. It does not store any personal data.
Functional
Functional cookies help to perform certain functionalities like sharing the content of the website on social media platforms, collect feedbacks, and other third-party features.
Performance
Performance cookies are used to understand and analyze the key performance indexes of the website which helps in delivering a better user experience for the visitors.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics the number of visitors, bounce rate, traffic source, etc.
Advertisement
Advertisement cookies are used to provide visitors with relevant ads and marketing campaigns. These cookies track visitors across websites and collect information to provide customized ads.
Others
Other uncategorized cookies are those that are being analyzed and have not been classified into a category as yet.
SAVE & ACCEPT